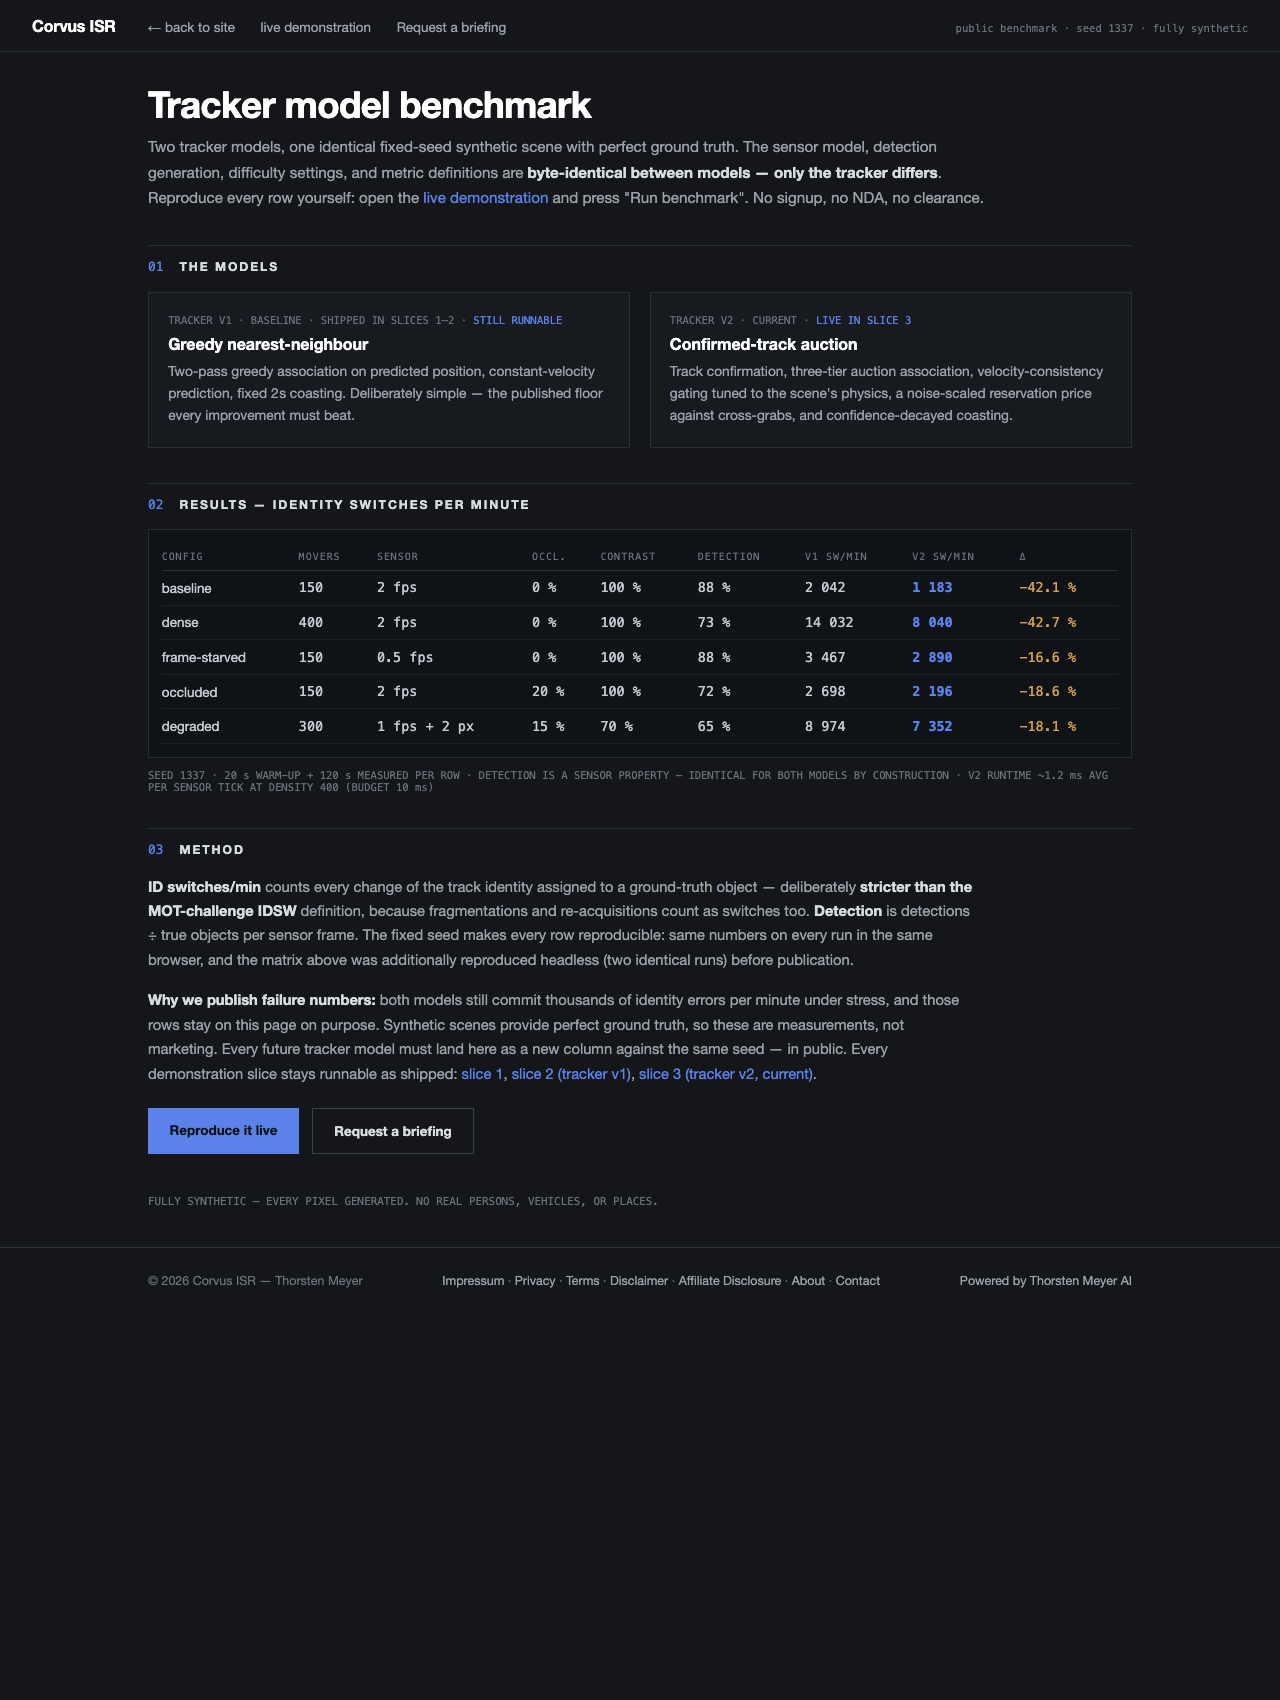
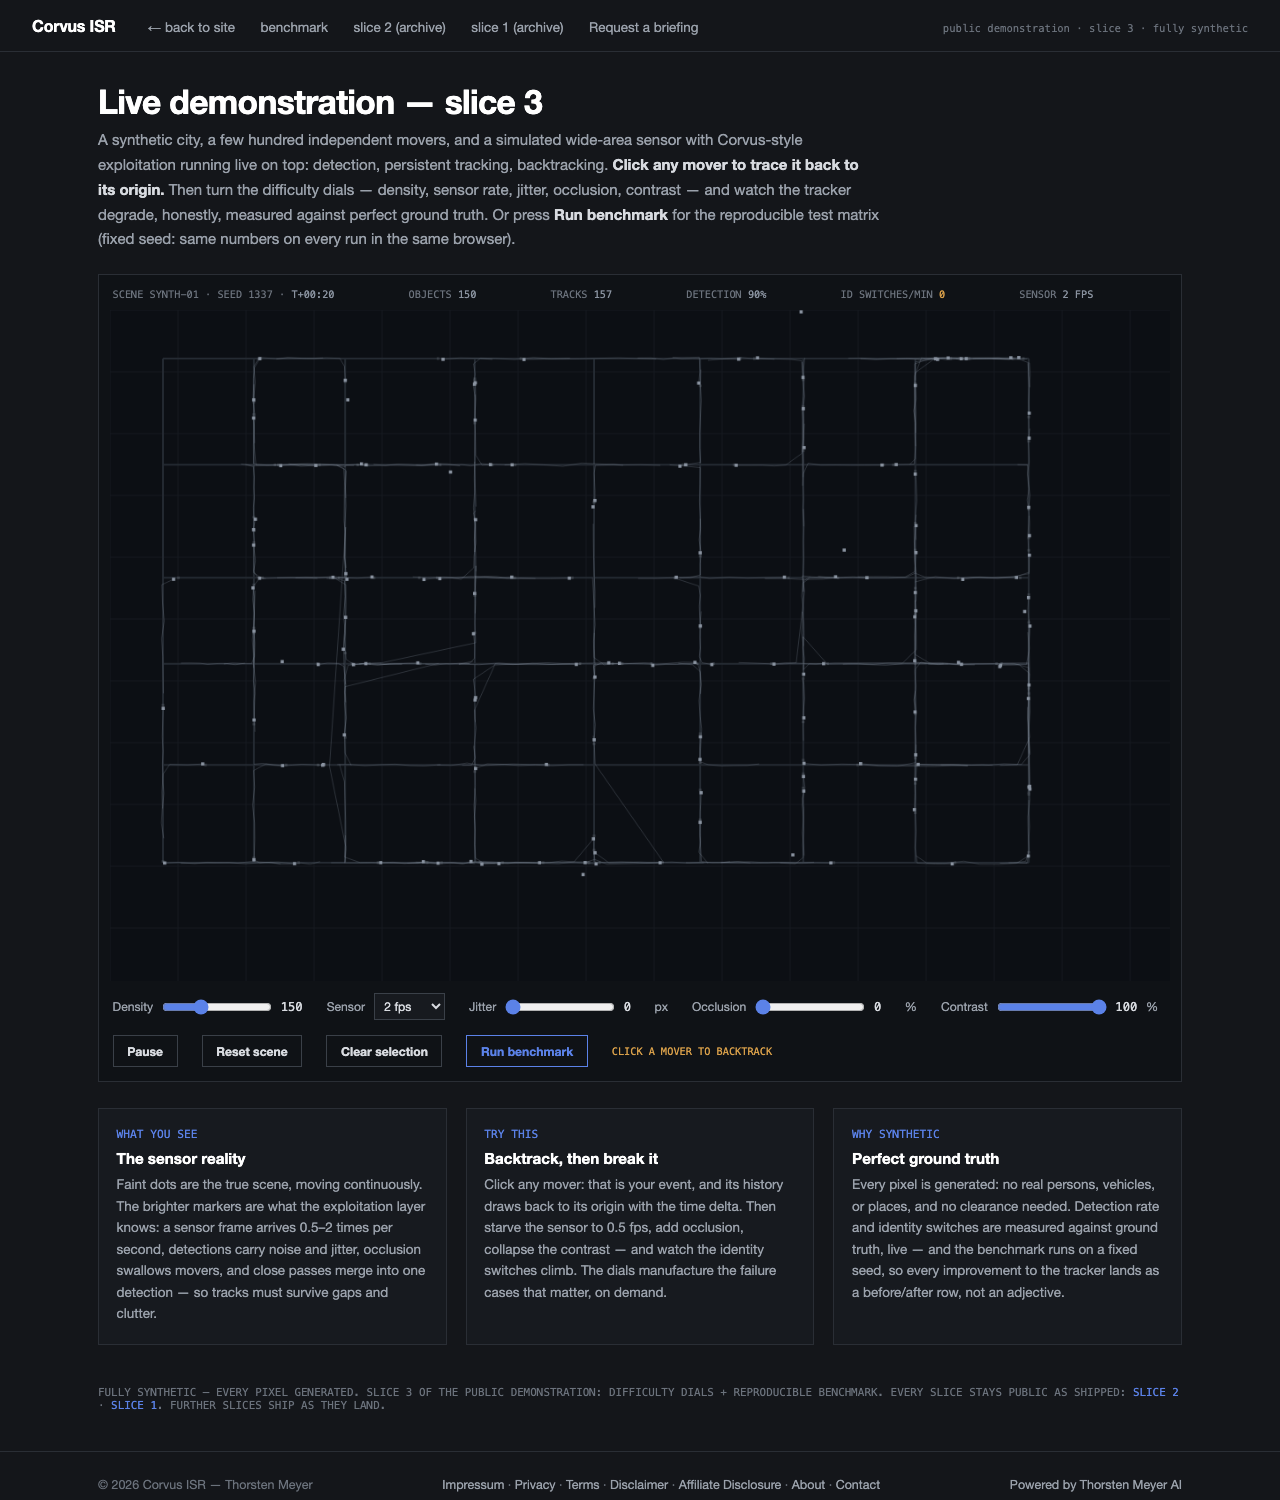
Corvus ISR, a leading provider of wide-area motion imagery (WAMI) exploitation products, has published a detailed public tracker benchmark that compares two distinct tracking models on an identical synthetic scene. This benchmark uses a fixed seed (seed 1337) to generate reproducible, perfect ground truth data, enabling a rigorous, apples-to-apples evaluation of tracker performance under controlled conditions.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
The baseline model, v1, employs a simple two-pass greedy association with constant-velocity prediction and a fixed 2-second coasting period. In contrast, the more advanced v2 uses a three-tier auction association, velocity-consistency gating, and noise-scaled reservation pricing to improve tracking accuracy. Both models were tested under various scenarios, including dense, occluded, and frame-starved conditions, providing a comprehensive picture of their robustness.
Results show that, in the baseline configuration with 150 movers at 2fps, ID switches per minute dropped from 2,042 to 1,183—a 42.1% reduction. Under more demanding conditions, such as dense scenes with 400 movers, the ID switches decreased from 14,032 to 8,040, a significant 42.7% improvement. These numbers are deliberately published to reflect the models’ failure modes clearly, as synthetic scenes provide perfect ground truth for honest measurement, not marketing.
Why is this important? Because every tracker will make errors—often thousands of identity switches per minute under stress. Publishing these figures openly demonstrates transparency and pushes the field toward better solutions. This approach aligns with the scientific method, where measured failures inform future development rather than relying solely on success stories.
From an engineering perspective, v2 achieves an average processing time of roughly 1.2 milliseconds per sensor tick at a density of 400 objects. Even in worst-case scenarios, it stays within a 5ms window, maintaining real-time performance. Curious readers can verify these results themselves by visiting the live demo and pressing “Run benchmark”—no signup or NDA required. This open, synthetic environment ensures every detail is generated, not real, providing a fully controlled setting for rigorous testing.
For science-minded audiences, understanding that these benchmarks rely on synthetic scenes with perfect ground truth highlights the importance of methodology in performance assessment. The fixed-seed matrix ensures reproducibility, making it possible for anyone to verify results precisely. Publishing honest, detailed failure metrics sets a new standard for transparency in tracking technology and invites the community to improve with clear, measurable goals.
Learn more by exploring the public benchmark and reproduce it live. We encourage you to run the benchmark yourself to see how different models perform under identical conditions, fostering a more transparent and scientific approach to tracker development.
Popular right now

iRobot Roomba 105 Robot Vacuum with LiDAR Navigation

Vitamix VX1 Professional-Grade Blender, 64 oz, Black

KitchenAid Artisan 5-Quart Tilt-Head Stand Mixer, Almond Cream
As an affiliate, we earn on qualifying purchases.